Rate limiting constitutes the primary defensive perimeter for modern web APIs, distributed microservices, and cloud infrastructure. From shielding backend databases against Distributed Denial of Service (DDoS) traffic spikes and brute-force credential stuffing attacks to enforcing multi-tenant SaaS monetization tiers, rate limiting ensures fair resource allocation and predictable service availability. Selecting and implementing the appropriate rate-limiting algorithm directly impacts latency, burst accommodation, and distributed memory overhead.
1. The Operational Necessity of Rate Limiting in Production Systems
Without rate limiting, public web endpoints and internal microservices operate under constant operational vulnerability:
- Resource Starvation (Noisy Neighbor Problem): In multi-tenant cloud environments, an unconstrained client executing runaway polling loops can saturate connection pools and CPU cores, degrading service quality for all other tenants.
- Cascading System Failure: Sudden traffic spikes can overwhelm downstream databases, triggering queue buildup, connection timeouts, thread pool starvation, and cascading microservice collapse.
- Economic and Billing Attacks: Unchecked consumption of third-party metered APIs (such as OpenAI LLM tokens, Twilio SMS gateways, or cloud vector databases) can rack up thousands of dollars in fraudulent infrastructure fees within minutes.
- Credential Stuffing and Brute Force: Automated bots submitting millions of password guesses against authentication endpoints will eventually compromise accounts unless throttled.
- Data Scraping and Harvesters: Unrestricted scrapers can aggressively crawl proprietary catalog databases, degrading site responsiveness for legitimate human end users.
2. Algorithmic Deep Dive: The Four Principal Rate-Limiting Models
Software architects deploy four primary mathematical algorithms to enforce request limits:
A. Fixed Window Counter Algorithm
The Fixed Window algorithm divides the timeline into fixed chronological intervals (e.g., 1 minute). A counter is maintained for each window.
- Incoming requests increment the current window’s counter.
- If the counter exceeds the threshold (e.g., 100 requests/minute), subsequent requests return
HTTP 429 Too Many Requests. - When the next window boundary arrives, the counter resets to zero.
The Fatal Flaw (Boundary Burst Spike): A client can submit 100 requests at 00:00:59 (the end of window 1) and another 100 requests at 00:01:01 (the start of window 2). Over that 2-second interval, the backend processes 200 requests—twice the intended maximum capacity!
B. Sliding Window Log Algorithm
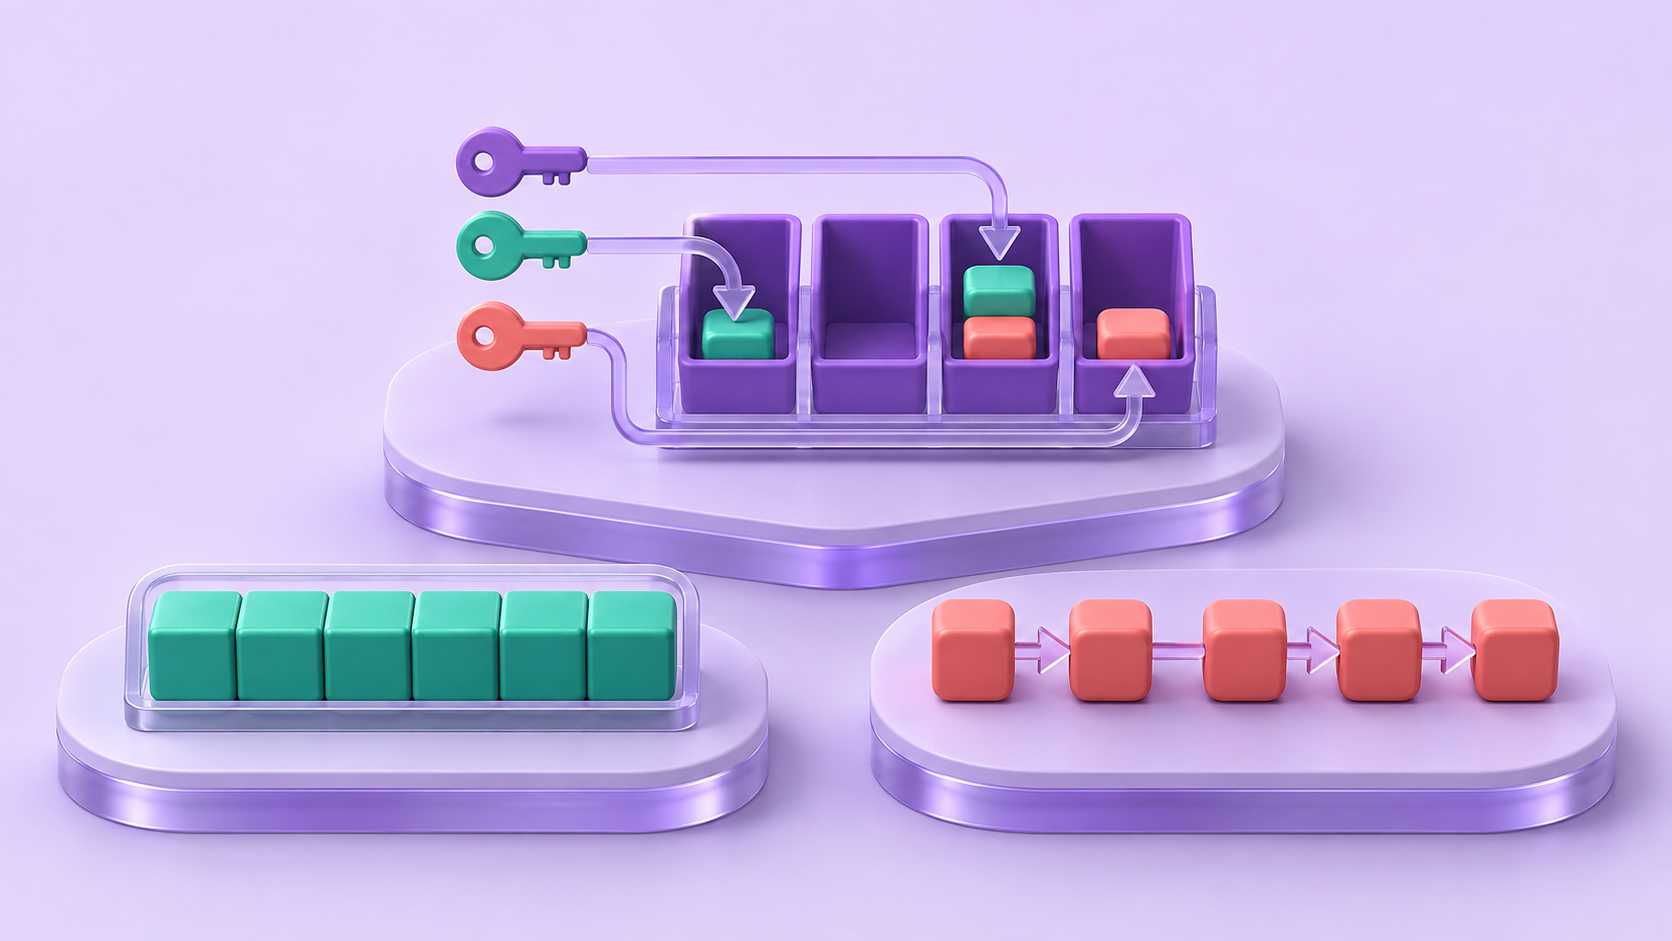
The Sliding Window Log algorithm completely eliminates boundary spikes by recording the exact timestamp of every incoming request in a sorted set (e.g., Redis ZSET):
- Upon receiving a request, purge all timestamps older than
current_time - window_size. - Count the remaining timestamps in the log.
- If the count is below the limit, append the current timestamp and allow the request. Otherwise, reject with 429.
The Memory Trade-off: While mathematically exact, storing every individual timestamp consumes massive amounts of RAM under high traffic volumes, making it prohibitive for high-velocity public APIs.
C. Sliding Window Counter (Approximation)
Invented to combine the memory efficiency of Fixed Window with the precision of Sliding Window Log, this algorithm computes a weighted sum of the current and previous windows:
Estimated Requests = Current Window Count + (Previous Window Count * (1 – Current Window Time Progress))
For example, if the limit is 100/minute, the previous minute had 100 requests, the current minute has 30 requests, and we are 30% through the current minute: Estimated = 30 + (100 * 0.70) = 100. Any additional request is rejected. This consumes only two integers in memory while bounding burst traffic with 99.9% accuracy.
D. Token Bucket Algorithm
Used by Amazon Web Services (AWS) and Stripe, the Token Bucket algorithm models a container of capacity C that refills with tokens at a constant rate r (tokens per second):
- Each request consumes 1 token from the bucket.
- If tokens are available, the request proceeds immediately.
- If the bucket is empty, the request is rejected or queued.
- Burst Accommodation: If no requests arrive for a period, the bucket fills up to capacity C. A sudden burst of C requests can be processed immediately without throttling, after which requests are capped at rate r.
E. Leaky Bucket Algorithm
Often contrasted with Token Bucket, the Leaky Bucket algorithm models a buffer queue that processes requests at a strictly constant rate, like water leaking out of a punctured bucket:
- Incoming requests enter a FIFO queue.
- If the queue is full, incoming requests overflow and are dropped (429).
- A worker process pulls requests from the queue at a steady, fixed cadence.
- Smooth Traffic Shaping: Unlike Token Bucket which allows bursts, Leaky Bucket enforces completely smooth, uniform outbound request rates, ideal for downstream systems with sensitive concurrency limits.
3. Comparative Rate-Limiting Architectural Matrix
The following matrix evaluates the five rate-limiting algorithms across critical production metrics:
| Rate Limiting Algorithm | Burst Handling | Memory Footprint | Time Complexity | Accuracy | Ideal Production Use-Case |
|---|---|---|---|---|---|
| Fixed Window Counter | Poor (Double-limit boundary spikes) | O(1) – single integer | O(1) | Low (susceptible to boundary exploits) | Basic tier limits, non-critical scheduled batch tasks |
| Sliding Window Log | Exceptional (Zero burst vulnerabilities) | O(N) – stores every timestamp | O(log N) set operations | Absolute 100% precision | Low-volume sensitive security endpoints (Login, Password Reset) |
| Sliding Window Counter | Excellent (Smooth boundary transitions) | O(1) – two counters per client | O(1) | High (~99.9% approximation) | Cloudflare edge proxies, API Gateways (Kong, Envoy) |
| Token Bucket | Exceptional (Permits controlled bursts up to C) | O(1) – counter + timestamp | O(1) | High | Stripe API, AWS API Gateway, general microservice rate limits |
| Leaky Bucket | Zero bursts (Smooths traffic to fixed rate) | O(Capacity) – FIFO queue | O(1) | High | Video encoding queues, database ingestion pipelines, webhook dispatches |
4. Distributed Rate Limiting: Solving Race Conditions with Redis Lua Scripts
In modern multi-node architectures, application servers run behind load balancers. Rate limits must be coordinated across all servers using a shared distributed cache like Redis.
The Race Condition Trap (Check-Then-Act)
A naive distributed rate limiter performs two operations:
current = redis.get(user_id)if current < limit: redis.incr(user_id)
Under concurrent load, two independent API servers can execute step 1 simultaneously, reading current = 99, and both execute step 2, exceeding the limit of 100. This is a classic Check-Then-Act race condition.
Atomic Redis Lua Scripting
Redis executes Lua scripts as a single atomic transaction. No other commands can run concurrently while the Lua script is executing, guaranteeing 100% thread safety and eliminating race conditions in a single network round-trip.
5. Distributed Rate Limiting at Scale: Multi-Region Synchronization
When operating services across multi-region cloud infrastructures (such as US-East, EU-Central, and AP-Southeast), centralizing all rate-limiting checks in a single global Redis instance causes prohibitive cross-continent network latency penalties (e.g. 150ms per API call just to check a rate limit!).
Enterprise cloud architectures deploy two advanced multi-region solutions:
- Local Token Allocation with Asynchronous Quota Balancing: A central quota coordinator allocates a portion of the user’s rate budget to each region (e.g., 40% to US, 30% to EU, 30% to Asia). Regional gateways evaluate limits entirely against local in-memory Redis clusters in under 1 millisecond. An asynchronous background heartbeat process periodically reallocates unused tokens based on real-time traffic demand.
- Local In-Memory Batching (Client Daemon Leases): Gateway nodes maintain in-memory counters and periodically batch increment counts to Redis every 50ms rather than firing a network round-trip on every single HTTP request. This transforms millions of individual requests into compact bulk increments.
6. Production Engineering Implementation: Token Bucket Engine in Python
Below is an enterprise-grade Python module demonstrating an atomic, lazy-refill Token Bucket algorithm suitable for distributed systems:
7. HTTP Standard Response Headers and Client Retry Coordination
To facilitate smooth client integration, RFC 6585 and IETF drafts standardize rate-limiting HTTP headers:
- HTTP Status 429 Too Many Requests: Standard response returned when rate limits are exceeded.
- Retry-After: Indicates the number of seconds (or HTTP date) the client must wait before retrying. Clients must respect this header using exponential backoff with jitter to prevent thunderous herd retries.
- X-RateLimit-Limit: The maximum number of allowed requests in the active window period.
- X-RateLimit-Remaining: The number of remaining available requests in the active window.
- X-RateLimit-Reset: Epoch timestamp indicating when the current quota will fully replenish.
8. Frequently Asked Questions (FAQ)
Q: What is the difference between Token Bucket and Leaky Bucket?
Token Bucket allows controlled burst traffic up to the bucket capacity while maintaining an average rate. Leaky Bucket enforces a strictly uniform outbound flow rate, queuing incoming bursts and smoothing traffic without spikes.
Q: How does Redis execute atomic rate limiting?
Redis executes Lua scripts atomically in a single thread. The script reads the counter, checks limits, updates timestamps, and sets expiration TTLs without inter-thread interleaving, eliminating race conditions.
Q: What is the boundary burst problem in Fixed Window rate limiters?
A client can send their full quota at the very end of window 1 and another full quota at the very beginning of window 2, causing twice the allowed request volume to hit the server within a tiny time slice.
Q: What is Exponential Backoff with Jitter?
When a client receives HTTP 429, it doubles its wait time on subsequent retries (e.g. 1s, 2s, 4s, 8s) and adds random jitter (e.g. +/- 20%). Jitter desynchronizes clients, preventing all retrying clients from hitting the server at the exact same millisecond.
Q: Where should rate limiters be placed in system architecture?
Rate limiting is typically deployed at the edge layer (API Gateway like Kong/Envoy or CDN like Cloudflare) to drop malicious or excessive traffic before it consumes internal bandwidth and server CPU cycles.
Q: How do rate limiters track client identity?
Public APIs track client IP addresses (via X-Forwarded-For). Authenticated APIs track unique API Keys or User IDs. Advanced systems use composite keys (User ID + Endpoint Path + IP).
Q: What is the memory consumption of Sliding Window Counter?
Sliding window counter requires storing only two integers per client (previous count, current count) and a timestamp, achieving tiny O(1) memory overhead comparable to fixed window algorithms.
Q: Can rate limiting be bypassed using IP spoofing?
Attackers can forge client IP headers if the API Gateway improperly trusts raw X-Forwarded-For headers from untrusted reverse proxies. Production gateways must only trust IP headers appended by verified upstream load balancers.
Q: What is Tiered Rate Limiting?
Tiered rate limiting assigns different thresholds based on business customer tiers (e.g. Free Tier = 60 req/min, Professional = 1,000 req/min, Enterprise = 50,000 req/min).
Q: What is Distributed Rate Limiting synchronization lag?
In multi-datacenter setups, syncing Redis clusters across continents introduces latency. Architectures use local cluster tokens or asynchronous gossip protocols to share quota usage without cross-region round trips.
Q: How does gRPC enforce rate limits?
gRPC implements rate limiting via server interceptors, inspecting incoming metadata headers and aborting requests with status code grpc.StatusCode.RESOURCE_EXHAUSTED.
Q: What is Lazy Token Refill in Token Bucket implementations?
Instead of running a background timer thread that constantly adds tokens every second, lazy refill calculates how many tokens should have been added based on the elapsed time since the last request, saving immense CPU overhead.
9. Architectural Conclusion and Engineering Recommendations
Rate limiting is a foundational defense mechanism for modern software platforms. When architecting API security perimeters:
- Standardize on Token Bucket for general web APIs to accommodate healthy traffic bursts without sacrificing throughput protection.
- Deploy Sliding Window Counter at edge reverse proxies for memory-efficient, boundary-safe rate enforcement across millions of unique IPs.
- Execute rate limit operations inside Atomic Redis Lua scripts to eliminate multi-server race conditions.
- Provide comprehensive RFC standard headers (Retry-After, X-RateLimit-*) to empower client SDKs with intelligent backoff coordination.