Dynamic Programming (DP) is an algorithmic paradigm designed to solve complex multi-stage decision problems by decomposing them into overlapping subproblems and enforcing optimal substructure. Beyond abstract mathematical puzzles, dynamic programming powers critical real-world infrastructure: from relational database query optimizers calculating join orders and bioinformatics gene-sequence alignments (Needleman-Wunsch) to packet scheduling queues, financial portfolio rebalancing engines, and machine learning reinforcement policies.
1. Mathematical Foundations: The Bellman Principle of Optimality
Formulated by Richard Bellman in the 1950s, the Bellman Principle of Optimality governs every valid dynamic programming formulation: ‘An optimal policy has the property that whatever the initial state and initial decision are, the remaining decisions must constitute an optimal policy with regard to the state resulting from the first decision.’
For a computational problem to admit a dynamic programming solution, it must satisfy two indispensable mathematical properties:
- Optimal Substructure: An optimal solution to the overarching problem contains within it optimal solutions to related subproblems. For instance, if the shortest path from vertex A to vertex C passes through intermediate vertex B, the sub-path from A to B must itself be the shortest possible path between A and B. If a cheaper path from A to B existed, we could splice it in to produce a shorter total journey from A to C, contradicting the premise.
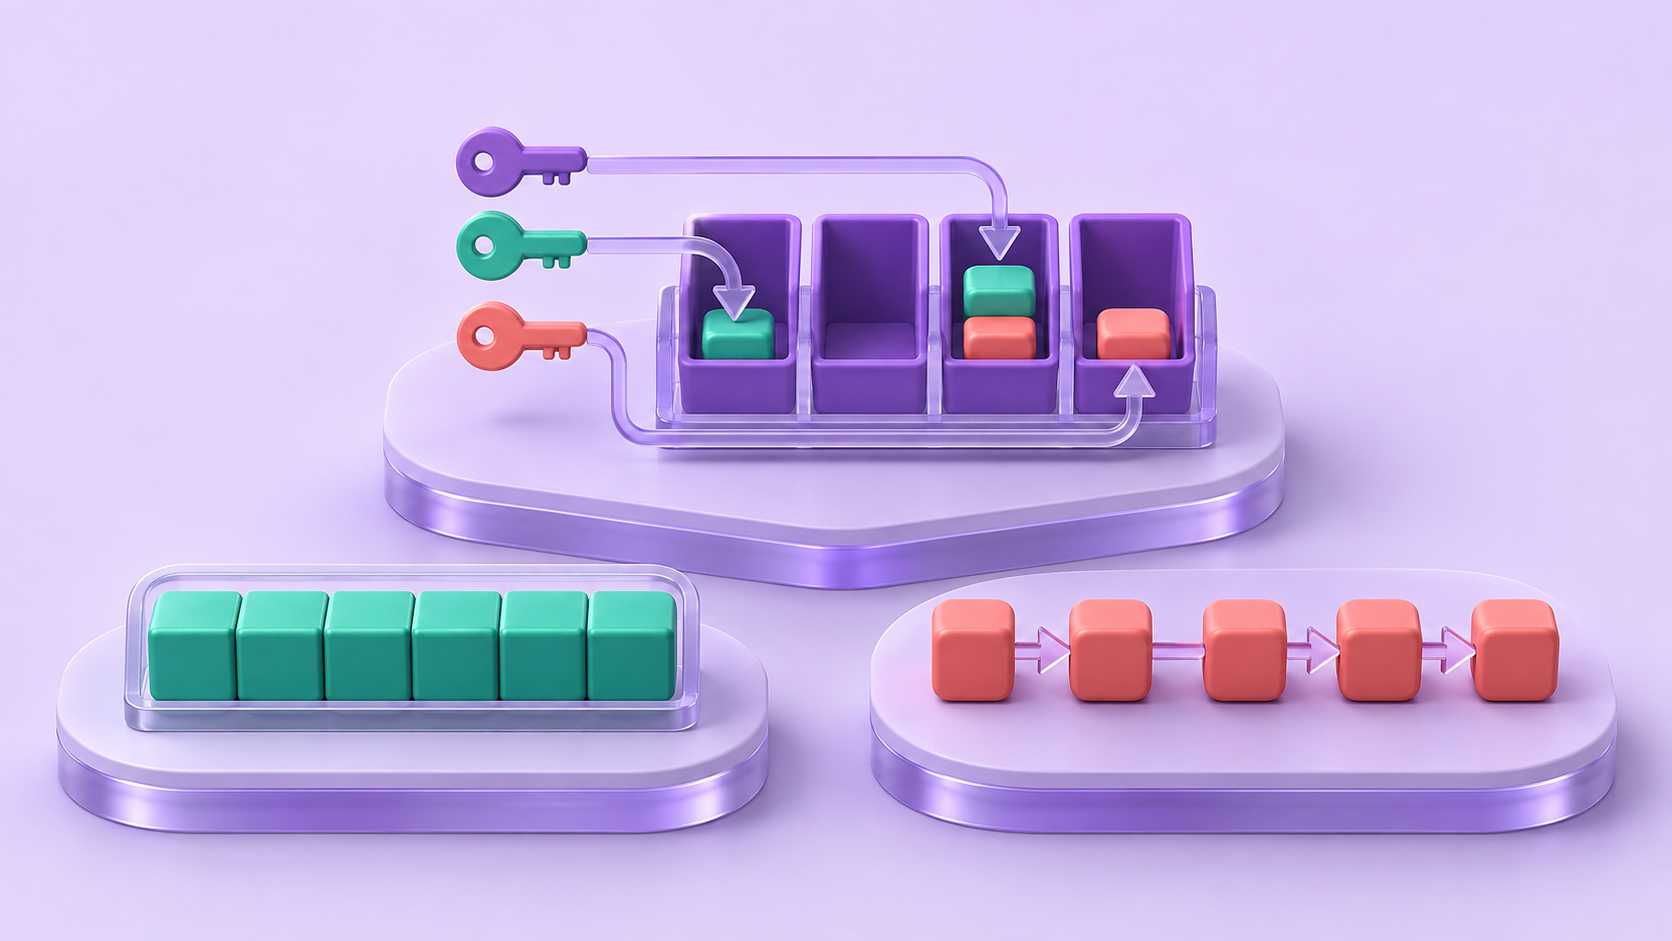
- Overlapping Subproblems: A naive recursive formulation revisits identical subproblems exponentially many times rather than generating novel subproblems at each step. This distinguishes DP from Divide-and-Conquer paradigms (like Merge Sort or Quicksort), where subproblems are strictly disjoint. By caching subproblem results, dynamic programming guarantees each subproblem is evaluated exactly once.
Without optimal substructure, greedy decisions and dynamic programming both collapse, forcing the algorithm designer into exhaustive search or branch-and-bound exploration. Without overlapping subproblems, memoization merely wastes allocation overhead without saving CPU cycles.
2. Top-Down Memoization vs. Bottom-Up Tabulation
Engineering a dynamic programming solution requires choosing between two fundamental architectural implementation styles, each presenting distinct CPU cache and call stack implications:
| Architectural Metric | Top-Down (Memoized Recursion) | Bottom-Up (Iterative Tabulation) |
|---|---|---|
| Evaluation Direction | Formulates root problem first; descends lazily into subproblems as needed. | Evaluates base cases first; iteratively computes all intermediate states toward the target. |
| Call Stack Overhead | High; incurs function call frame overhead and risks StackOverflow on deep recursions. | Zero call stack overhead; runs in flat iterative loops. |
| State Space Coverage | Sparse evaluation; only computes states strictly required along the active branch. | Exhaustive evaluation; typically computes all subproblem combinations in the table. |
| CPU Cache Spatial Locality | Poor; tree traversal jumps through hash maps or scattered heap nodes. | Excellent; contiguous 1D or 2D array iterations maximize CPU prefetching and cache hits. |
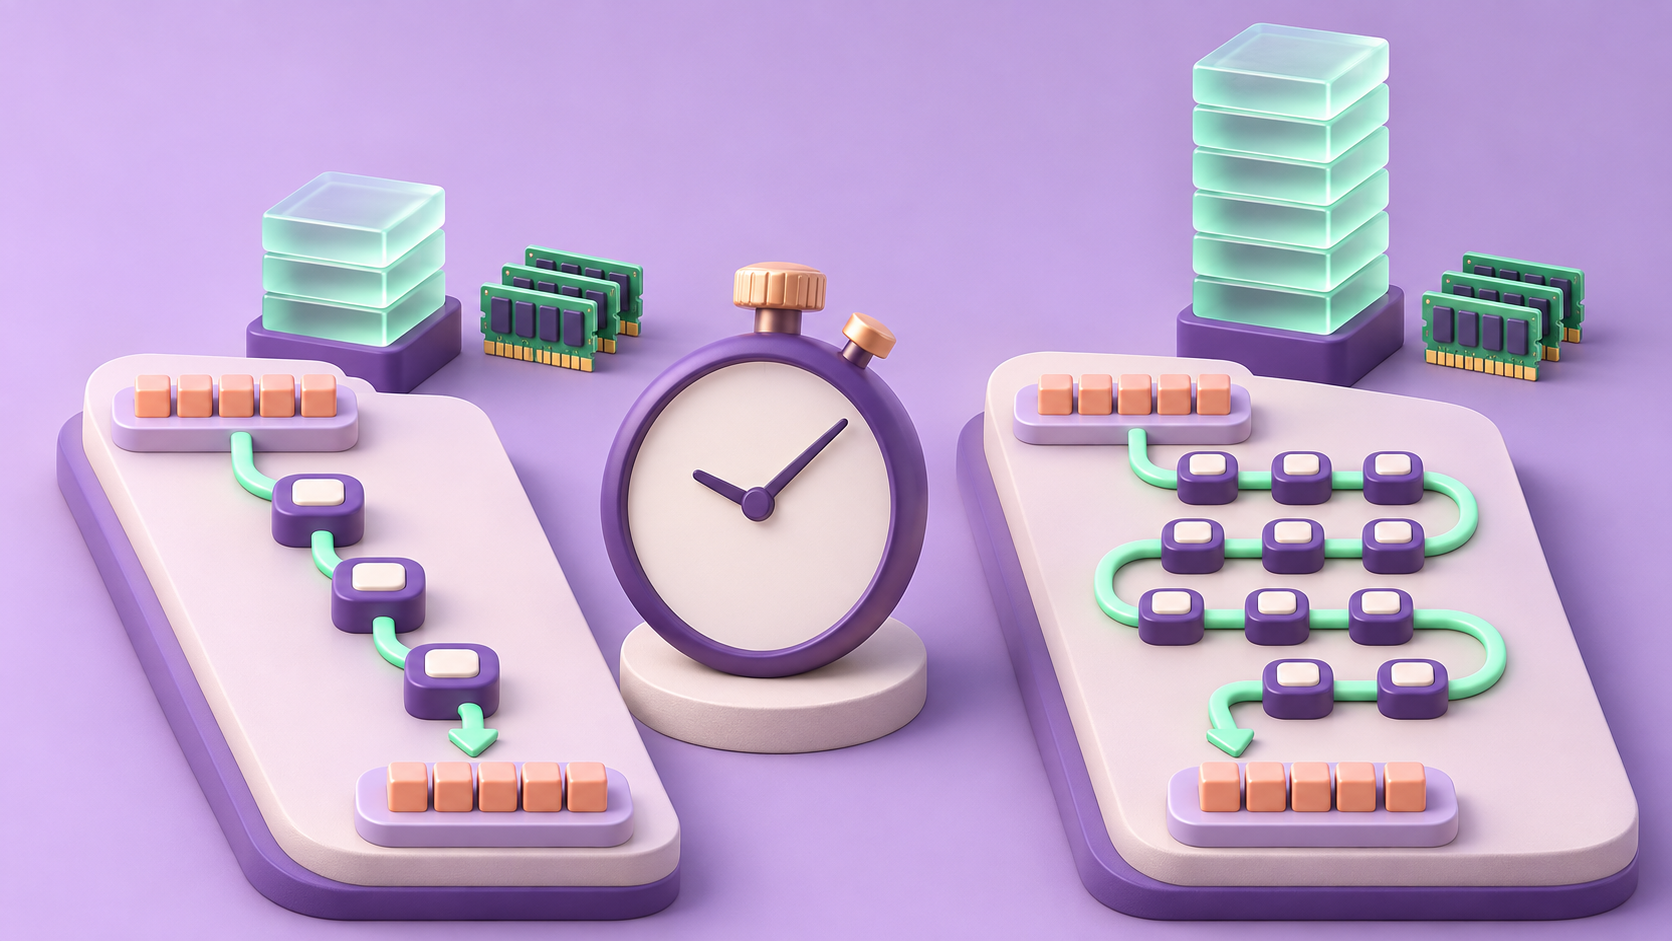
| Memory Footprint Optimization | Difficult; memo cache must retain states across dynamic branch calls. | Straightforward; sliding window or two-row rolling arrays allow massive space compression. |
In high-throughput systems programming (such as C++, Rust, or Go services), bottom-up tabulation is universally preferred for critical-path algorithms. Sequential iteration through flat primitive arrays maps cleanly to modern CPU L1/L2 caches and allows compiler auto-vectorization using SIMD instruction sets, delivering performance leaps of 5x to 20x over pointer-heavy hash-map memoization.
3. State Space Representation and Dimensionality Reduction Techniques
The true engineering art in dynamic programming lies in state space design. An overly broad state vector leads to combinatorial explosions in memory, while an incomplete state vector violates the Markovian property (where the future state depends solely on the current state and action, not the past trajectory).
Techniques for State Space Dimensionality Reduction
- Rolling Array (Sliding Window): When computing state dp[i][j], if transitions only depend on the immediate prior step dp[i – 1][k], the entire i – 2 through 0 history can be discarded. This collapses a 2D table of size O(N * M) into two rows of size O(M), or even a single row traversed in reverse order. In heavy matrix chains, this reduces gigabytes of RAM down to mere kilobytes.
- Bitmask State Representation: For problems involving subsets of size N (where N <= 30), states can be encoded as integer bitmasks where the k-th bit indicates the inclusion or exclusion of element k. Bitwise operators (AND, OR, XOR, shifts) allow state transitions to execute in single-cycle CPU instructions. This powers classic Traveling Salesperson Problem (TSP) algorithms, reducing factorial O(N!) exploration to O(N^2 * 2^N).
- Convex Hull Trick (CHT) & Knuth’s Optimization: For interval DP problems with quadrangle inequalities or linear recurrence transitions, geometric duality reduces transition complexity from O(N) to O(1) or O(log N), transforming O(N^3) algorithms into O(N^2) or O(N log N).
- Divide and Conquer Optimization: When the transition index opt(i, j) satisfies monotonicity across row boundaries (opt(i, j) <= opt(i, j+1)), a divide-and-conquer recursion can evaluate an entire row of DP states in O(N log N) rather than naive O(N^2), fundamentally altering batch processing performance.
4. Deep Dive: The Knapsack Family of Optimization Problems
The Knapsack problem represents the prototypical constrained optimization problem. We explore the three principal archetypes encountered in production engineering:
A. 0/1 Knapsack (Binary Decision)
Given N items, each with weight w_i and value v_i, and a maximum container capacity W, determine the maximum value achievable without exceeding W, where each item can be selected at most once.
The mathematical recurrence relation is defined as:
dp[i][w] = dp[i-1][w] (if w_i > w)
dp[i][w] = max(dp[i-1][w], dp[i-1][w – w_i] + v_i) (if w_i <= w)
By iterating capacity w backward from W down to w_i, this can be solved in a single 1D array of size W + 1, achieving O(N * W) pseudo-polynomial time and O(W) auxiliary space. This backward traversal invariant prevents an item from being mistakenly incorporated multiple times within the same pass.
B. Unbounded Knapsack (Infinite Multiplicity)
In the unbounded variant, an infinite supply of each item is available. The recurrence changes subtly:
dp[w] = max(dp[w], dp[w – w_i] + v_i)
Here, the capacity loop runs forward from w_i up to W, deliberately allowing the current item to be selected multiple times within the same iteration pass. This formulation directly models currency exchange change-making systems and continuous asset replication algorithms.
C. Bounded Knapsack with Binary Dequantization
When each item i has an integer quantity limit c_i, naive conversion to 0/1 knapsack yields O(W * sum(c_i)) complexity. By decomposing each count c_i into powers of two (1, 2, 4, 8, … remainder), we reduce the effective number of items to O(sum(log c_i)), shrinking runtime to O(W * sum(log c_i)). This exponential compaction prevents system timeouts when processing items with high numerical inventory caps.
5. Enterprise Implementation: Space-Optimized Multi-Constraint Knapsack Engine
Below is an enterprise-grade Python implementation of a 2D multi-constraint knapsack problem (such as balancing CPU and RAM limits in cloud pod scheduling with full traceback reconstruction):
6. Real-World Applications Across Industrial Computing
Dynamic programming is far from a theoretical classroom concept. Modern hyperscale architectures depend heavily on dynamic programming optimizations across multiple critical sectors:
- Database Cost-Based Query Optimizers (CBO): When a relational database like PostgreSQL or CockroachDB evaluates an SQL query joining 10 tables, there are 10! / 2 possible join tree combinations. The System R algorithm uses dynamic programming over table subset bitmasks to find the minimal I/O disk cost in O(3^N) time instead of factorial O(N!).
- Bioinformatics Sequence Alignment: The Needleman-Wunsch (global) and Smith-Waterman (local) algorithms align genomic DNA sequences using 2D DP matrices with gap penalty scoring, identifying evolutionary mutations across billions of base pairs in cancer research and viral tracking.
- Audio and Speech Processing (Viterbi Algorithm): Hidden Markov Models (HMMs) utilize the Viterbi dynamic programming recurrence to find the most probable sequence of hidden phonemes given noisy acoustic waveform observations, forming the basis of legacy telecom codecs and automated speech recognition systems.
- Network Packet Flow Control & Bandwidth Allocation: Router queue management protocols utilize bounded knapsack dynamic programming to pack variable-sized TCP packets into fixed-size transmission frames (MTU), minimizing fragmentation and maximizing throughput across high-speed backbone fibers.
- Financial Portfolio Optimization: Quantitative trading systems employ stochastic dynamic programming (Bellman equations under uncertainty) to determine continuous portfolio rebalancing thresholds, balancing transactional slip costs against projected alpha gains.
7. Performance Profiling, Memory Alignment, and Cache Locality
When benchmarking dynamic programming code in production environments, CPU cache miss rates frequently outweigh Big-O algorithmic scaling. A naive 2D matrix allocation in languages like Java or Python creates an array of object pointers, where each row is an independently allocated heap structure scattered across memory. When traversing columns, CPU cache lines (typically 64 bytes) are constantly evicted, triggering severe memory stalls.
To achieve maximum operational performance:
- Flatten 2D Grids to 1D: Allocate a single contiguous primitive array of size
N * Mand index elements usingindex = i * M + j. This guarantees sequential memory layout and enables CPU prefetchers to anticipate sequential reads. - Row-Major Traversal: Ensure inner iteration loops iterate across contiguous memory columns rather than striding down rows. In C and C++, row-major order aligns with hardware memory banking.
- SIMD Vectorization: For operations like Longest Common Subsequence (LCS) or Levenshtein edit distance, bit-parallel dynamic programming (Myers’ algorithm) packs state differentials into 64-bit or 256-bit AVX integer registers, evaluating up to 64 character comparisons simultaneously in a single clock cycle.
8. Frequently Asked Questions (FAQ)
Q: What distinguishes dynamic programming from greedy algorithms?
Greedy algorithms make a locally optimal choice at each step without ever reconsidering past decisions, which only yields globally optimal outcomes for specific matroid structures. Dynamic programming evaluates all valid subproblem combinations and accounts for non-local downstream consequences before finalizing choices.
Q: Why is the Knapsack problem considered NP-complete if DP solves it in O(N*W)?
The O(N*W) time complexity is pseudo-polynomial, not polynomial. The parameter W is represented in memory using log2(W) bits. As the numerical magnitude of W grows exponentially with input bit-length, the runtime is exponential relative to the input representation length.
Q: How can stack overflow errors be prevented in top-down memoization?
Stack overflow occurs when the recursion depth exceeds sys.getrecursionlimit(). You can either increase the recursion ceiling, rewrite the logic into bottom-up tabulation, or implement a manual heap-allocated call stack using a state machine loop.
Q: What is the space complexity advantage of traversing backward in 0/1 knapsack?
Traversing capacity backward ensures that when computing dp[w], the referenced value dp[w – w_i] represents the state from the previous item iteration, preventing an item from being mistakenly incorporated multiple times within the same pass.
Q: When should Bitmask Dynamic Programming be avoided?
Bitmask DP scales as O(N^2 * 2^N). When N exceeds 22 to 24, the state space exceeds several million elements, causing memory pressure. Beyond N=30, 2^N exceeds one billion states, making bitmask dynamic programming computationally intractable.
Q: Can dynamic programming be parallelized across multi-core GPUs?
Yes. In bottom-up DP matrices, dependencies often lie along anti-diagonals (wavefront parallelism). All cells along the same anti-diagonal can be evaluated independently in parallel threads across GPU compute units.
Q: What role does DP play in modern Large Language Models (LLMs)?
Beam search decoders and KV-cache re-use mechanisms in transformer inference leverage dynamic programming principles to efficiently explore token probability trajectories without repeating redundant attention computations.
Q: What is Knuth’s Optimization in dynamic programming?
Knuth’s optimization applies to interval DP problems where the optimal splitting point opt[i, j] satisfies monotonicity: opt[i, j-1] <= opt[i, j] <= opt[i+1, j]. This tightens the inner loop search, reducing asymptotic runtime from O(N^3) to O(N^2).
Q: How do floating-point weights affect dynamic programming?
Dynamic programming requires discrete state indices. Continuous floating-point weights cannot index arrays directly. Practitioners must either scale and quantize weights into integer bins or utilize branch-and-bound linear programming.
Q: What is the difference between Smith-Waterman and Needleman-Wunsch algorithms?
Needleman-Wunsch performs global sequence alignment, scoring the entire sequence from start to finish. Smith-Waterman performs local alignment, resetting negative cell scores to zero to detect highly conserved localized substrings.
Q: How does memoization handle non-deterministic or side-effecting operations?
Dynamic programming requires referential transparency: given identical input parameters, a subproblem must strictly produce identical outputs. Any dependency on external clock time, random number generators, or mutable global state violates DP correctness and causes corrupted memo tables.
Q: What is the Convex Hull Trick (CHT) in dynamic programming optimization?
The Convex Hull Trick optimizes DP transitions of the form dp[i] = min(dp[j] + m_j * x_i + c_j) where each transition behaves like a linear function y = m * x + c. By maintaining the lower convex hull of lines in a deque or Li Chao tree, the optimal transition can be queried in O(1) or O(log N) rather than scanning all prior j states.
9. Architectural Conclusion and Engineering Recommendations
Mastery of dynamic programming requires recognizing underlying recurrence invariants, carefully designing minimal state representations, and engineering space-reduction techniques to optimize hardware cache performance. In modern high-throughput architectures, transitioning from naive memoization to cache-aligned bottom-up tabulation is often the critical difference between sub-second SLA compliance and fatal out-of-memory crashes. Whether structuring cloud orchestration queues or computing sequence alignments at scale, dynamic programming remains one of the most powerful and mathematically grounded tools in the software architect’s arsenal.