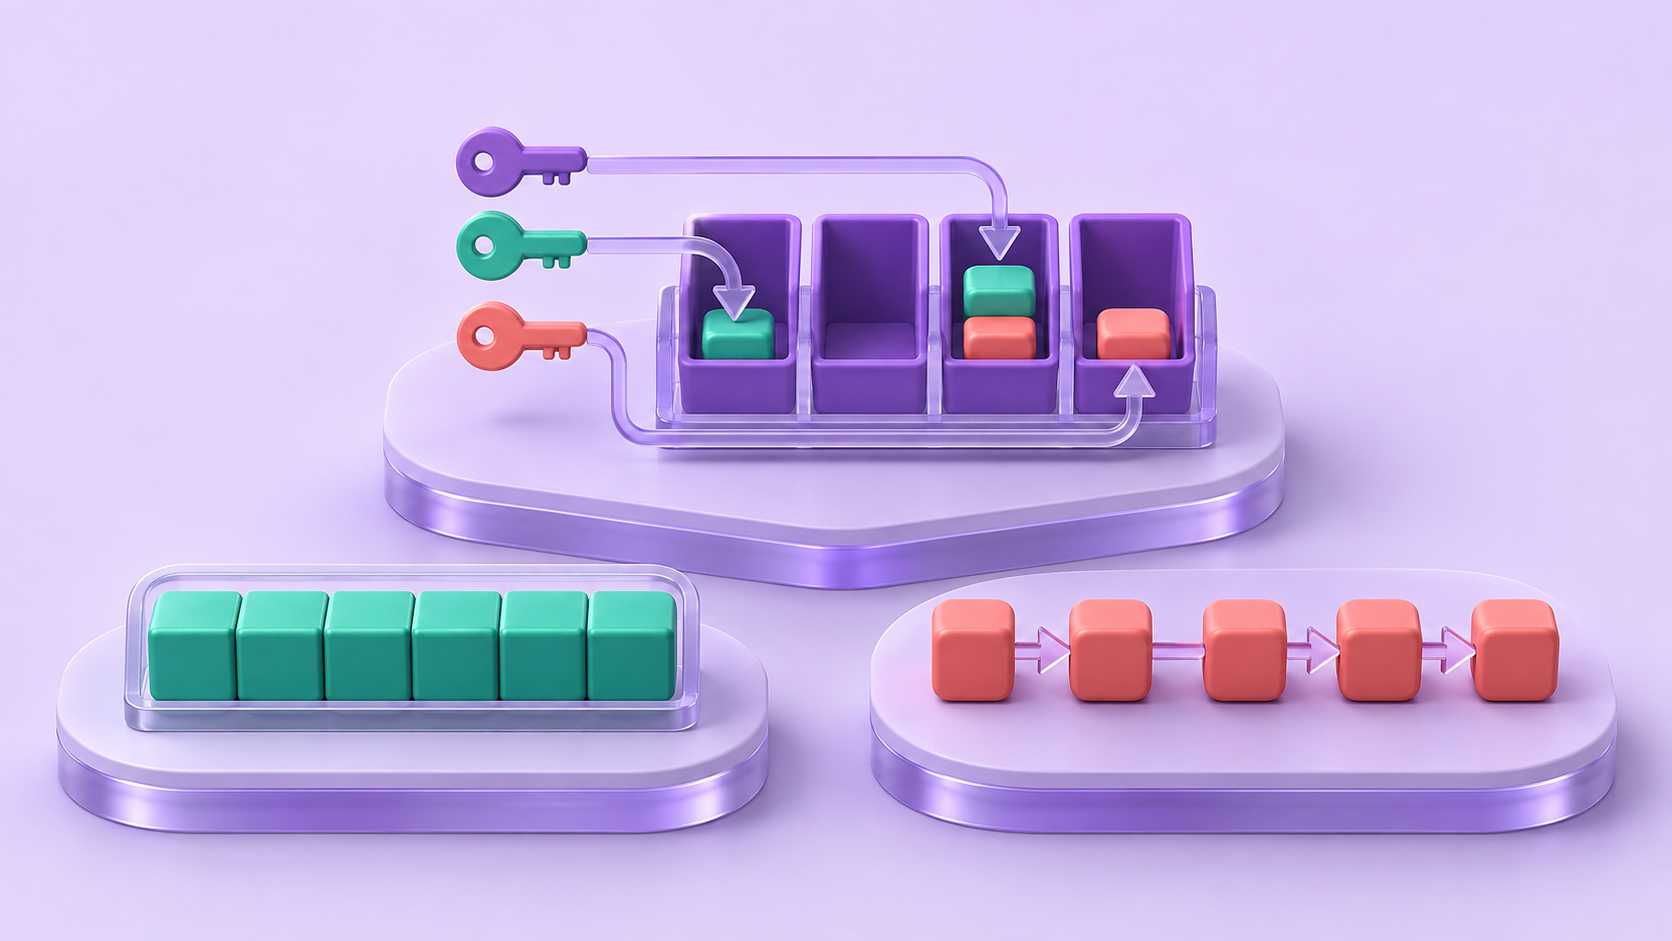
Hash tables are the undisputed workhorses of software engineering, providing theoretical O(1) average-time complexity for key insertions, lookups, and deletions. However, in modern computer architecture where CPU clock frequencies outstrip DRAM access speeds by orders of magnitude, textbook implementations based on separate chaining (linked lists) degrade catastrophically due to pointer chasing and CPU cache misses. Modern high-performance runtimes—including Rust’s HashMap (SwissTable), Google’s Abseil FlatHashMap, and ClickHouse data engines—rely on cache-conscious open-addressing algorithms.
1. The Classical Failure: Why Separate Chaining Breaks on Modern Hardware
Textbook hash tables introduced in introductory computer science curricula typically use Separate Chaining. An array of buckets holds pointers to heap-allocated linked lists. When two keys hash to the same bucket index, the new element is prepended or appended to the corresponding linked list.
While mathematically clean and simple to implement, separate chaining exhibits fatal hardware inefficiencies:
- Pointer Chasing: Each node in a linked list is independently allocated on the heap, scattering memory across virtual memory space. Iterating through the chain incurs multiple L3 cache misses and TLB misses.
- Memory Overhead: Every single key-value entry carries 8 or 16 bytes of next-pointer overhead. For small primitive keys (e.g., 64-bit integers), the pointer overhead exceeds the payload size!
- Poor SIMD Parallelism: Linked lists cannot be vectorized using modern CPU vector instruction sets (AVX2, AVX-512, ARM NEON).
To overcome these limitations, high-throughput systems deploy Open Addressing: all elements are stored directly within a single contiguous array, eliminating heap pointer indirections entirely.
2. Linear Probing and The Dreaded Primary Clustering Problem
The most basic open addressing strategy is Linear Probing: if bucket h(k) is occupied, inspect h(k) + 1, h(k) + 2, and so forth until an empty slot is encountered.
While linear probing provides phenomenal CPU cache locality (adjacent array slots reside on the same 64-byte hardware cache line), it suffers from Primary Clustering. As the table load factor exceeds 50%, contiguous blocks of occupied slots merge into long unbroken chains. Any key hashing anywhere into the cluster lengthens the cluster even further, causing insertion and lookup latencies to degrade from O(1) to O(N).
3. Robin Hood Hashing: Equalizing Probe Sequence Lengths
Invented by Pedro Celis in 1986, Robin Hood Hashing revolutionizes linear probing by enforcing a profound social maxim: ‘Take from the rich and give to the poor.’
The Probe Sequence Length (PSL) Invariant
For every element residing in the hash table, we track its Probe Sequence Length (PSL)—defined as the number of slots between its ideal hashed bucket and its current position:
PSL(entry) = (current_slot – ideal_slot) mod capacity
An entry with PSL = 0 is ‘rich’ (sitting right at its home bucket). An entry with PSL = 5 is ‘poor’ (pushed 5 slots away from home).
Robin Hood Insertion Mechanics
When inserting an incoming key, we probe sequentially through the array while incrementing the incoming item’s PSL:
- If an empty slot is reached, place the item and terminate.
- If the current slot contains an existing entry whose PSL is strictly smaller than the incoming item’s PSL (i.e., the existing entry is ‘richer’ than our incoming ‘poorer’ item), we steal the slot: the existing item is evicted, the incoming item takes its place, and the evicted item becomes the new incoming item, continuing the probe sequence.
This simple exchange dramatically compresses the variance of probe lengths across the table. While traditional linear probing suffers extreme tail latencies (some keys require 40 probes), Robin Hood hashing produces a tight, deterministic distribution of probe counts, allowing search operations to abort early once the current slot’s PSL is smaller than the probe count.
4. Hopscotch Hashing: Neighborhood Bounding for Fast Point Lookups
Invented by Maurice Herlihy, Nir Shavit, and Moran Tzafrir in 2008, Hopscotch Hashing guarantees that any key hashing to bucket i will strictly reside within a small fixed neighborhood of size H (typically H = 32 or 64, fitting into a single CPU cache line).
The Hop Bitmask Indicator
Every bucket maintains an H-bit integer mask (the hop information). The k-th bit of bucket i is 1 if and only if the item belonging to home bucket i is currently stored at offset i + k.
When inserting, if linear probing discovers an empty slot outside neighborhood H, the algorithm recursively searches backward for an intermediate entry that can be relocated into the empty slot, opening an available slot closer to the home bucket. This preserves deterministic O(1) worst-case lookup latencies and facilitates concurrent thread locking using single-word atomic CAS operations.
5. Cuckoo Hashing: Constant Worst-Case Lookups and Eviction Cycles
Introduced by Rasmus Pagh and Flemming Friche Rodler in 2001, Cuckoo Hashing offers a theoretical holy grail: strictly O(1) worst-case lookup time.
Two Hash Functions, Two Candidate Buckets
Cuckoo hashing deploys two independent hash functions, h_1(k) and h_2(k). Every key can only reside in exactly one of two physical locations: table[h_1(k)] or table[h_2(k)].
- Lookup O(1) Guarantee: To find key K, check slot h_1(K). If not found, check slot h_2(K). If neither holds K, the key is definitively absent. No probing, no scanning, exactly 2 memory reads!
- Cuckoo Eviction Insertion: If slot h_1(K) is occupied by key X, the incoming key K kicks key X out of its nest (like a cuckoo bird). Key X is then relocated to its alternative position (h_2(X)). If that position is also occupied, the cascading eviction repeats. If an eviction cycle is detected (an infinite loop), the table automatically triggers a rehash with fresh seed functions.
6. The Pinnacle of Modern Architecture: Google SwissTable / Abseil FlatHashMap
Google’s SwissTable (adopted by Rust’s standard library and Abseil C++) represents the pinnacle of cache-conscious engineering by combining open addressing with SIMD-vectorized control bytes:
- The table stores metadata in a separate Control Byte Array: 1 byte per slot.
- The high 7 bits of the key’s hash form an h2 fingerprint; the lowest bit indicates empty/deleted/full state.
- During lookups, 16 control bytes are loaded into a single 128-bit SIMD register (SSE2 / NEON) and compared against the target fingerprint in one single CPU clock cycle!
- Only matching slots are inspected for full key equality, achieving unparalleled throughput and cache line efficiency.
7. Comparative Collision Resolution Architectural Matrix
The following matrix compares primary hash table collision algorithms across hardware and complexity benchmarks:
| Algorithm | Storage Paradigm | Lookup (Average / Worst) | Insertion Complexity | CPU Cache Coherence | Max Practical Load Factor |
|---|---|---|---|---|---|
| Separate Chaining | Array of Linked Lists | O(1) / O(N) | O(1) | Extremely Poor (heap pointer chasing) | Unlimited (degrades slowly) |
| Linear Probing | Open Addressing Array | O(1) / O(N) | O(1) amortized | Excellent (sequential cache lines) | 50% – 60% |
| Robin Hood Hashing | Open Addressing + PSL | O(1) / O(log N) | O(1) amortized | Excellent (compact localized scans) | 85% – 90% |
| Hopscotch Hashing | Open Addressing + Bitmask | O(1) / O(H) | O(1) amortized | Exceptional (fits in L1 cache line) | 90% – 95% |
| Cuckoo Hashing | Dual Array Slots | O(1) strictly worst-case | O(1) amortized (rehash on cycles) | Moderate (2 random cache reads) | 50% (higher with d-ary cuckoo) |
| SwissTable (SIMD) | Grouped Control Bytes + SIMD | O(1) / O(1) typical | O(1) amortized | State-of-the-art (16 slots evaluated per cycle) | 87.5% (7/8 capacity) |
8. Production Engineering Implementation: Robin Hood Hash Table in Python
Below is an enterprise-grade Python implementation of Robin Hood hashing featuring PSL tracking, eviction swaps, and early-abort search loops:
9. Frequently Asked Questions (FAQ)
Q: Why does Separate Chaining cause frequent CPU cache misses?
In separate chaining, every node in a linked list is allocated independently on the heap. When traversing the collision list, memory addresses jump unpredictably across DRAM, evicting cache lines and stalling the CPU pipeline.
Q: What is Probe Sequence Length (PSL) in Robin Hood hashing?
PSL represents the distance (in slots) that an entry has moved away from its original hashed bucket. It quantifies how ‘poor’ an entry is relative to its ideal storage position.
Q: How does Robin Hood hashing allow early search aborts?
Because the insertion rule swaps richer elements with poorer ones, probe lengths along a cluster are ordered. If the search reaches a slot whose recorded PSL is smaller than the current search step count, the target key is guaranteed not to exist.
Q: What causes infinite loops during Cuckoo hash insertions?
When the load factor becomes too high or multiple keys form a cyclic directed graph of alternate positions, evictions bounce indefinitely between slots. The table must detect cycles using an eviction counter and trigger an emergency rehash.
Q: What is the primary advantage of SwissTable / Abseil FlatHashMap?
SwissTable splits metadata into 1-byte control arrays and uses SIMD vector instructions (SSE2/AVX) to evaluate 16 buckets in parallel in a single clock cycle, eliminating scalar branching and accelerating lookups.
Q: Why can’t Cuckoo hashing achieve 90% load factors easily?
Classic 2-table Cuckoo hashing has a theoretical maximum load factor threshold of approximately 50%. Attempting to fill beyond 50% causes exponential increases in eviction cycle frequency. Using 3 or 4 hash functions (d-ary cuckoo) increases capacity to 90% at the cost of more lookups.
Q: How does Hopscotch hashing support thread-safe concurrent access?
Hopscotch bounds each key’s residence to a small neighborhood bitmask (e.g. 32 bits). A worker thread only needs to lock that localized 32-slot memory window using atomic compare-and-swap (CAS) operations, avoiding coarse-grained table locks.
Q: What is backward-shift deletion in open addressing?
When deleting a key in open addressing, leaving a tombstone can clutter the table. Backward-shift deletion shifts subsequent colliding entries one step backward until an empty slot or an entry with PSL=0 is found, keeping clusters tight.
Q: What is the impact of table resize operations on tail latency?
Reallocating and rehashing an entire multi-gigabyte table causes noticeable latency spikes (stop-the-world pauses). High-availability systems use Incremental Rehashing (like Redis dict), migrating a small batch of buckets on each request.
Q: How does hash function quality influence open addressing?
Poor hash functions with weak bit diffusion produce immediate clustering, which degrades open addressing performance rapidly. Modern tables use fast, high-avalanche non-cryptographic hashes such as MurmurHash3, CityHash, or Wyhash.
Q: What is Quadratic Probing and why is Linear Probing often faster despite clustering?
Quadratic probing checks slots at offsets 1, 4, 9, 16 to avoid primary clustering. However, its non-sequential memory jumps miss CPU cache prefetchers. Linear probing remains faster on modern hardware because sequential slots reside in the same L1/L2 cache line.
Q: What is the space overhead of Robin Hood hashing compared to standard arrays?
Robin Hood hashing requires storing a small integer (typically 1 byte for PSL) alongside each slot or embedding it in the metadata, resulting in negligible space overhead (1 to 2 extra bytes per entry).
10. Architectural Conclusion and Engineering Recommendations
Modern cache-conscious hash table architectures illustrate how algorithmic theory must evolve alongside hardware microarchitecture. When selecting or implementing hash tables in performance-sensitive systems:
- Avoid classical Separate Chaining for critical hot-path caches due to severe pointer-chasing DRAM stalls.
- Select Robin Hood Hashing when implementing simple, zero-dependency open-addressing tables with high load factor resilience and bounded tail lookups.
- Adopt SwissTable / FlatHashMap paradigms with SIMD vectorization whenever maximum throughput on x86-64 or ARM64 server architectures is required.
- Deploy Incremental Rehashing to eliminate latency spikes and SLA violations during table capacity expansions.