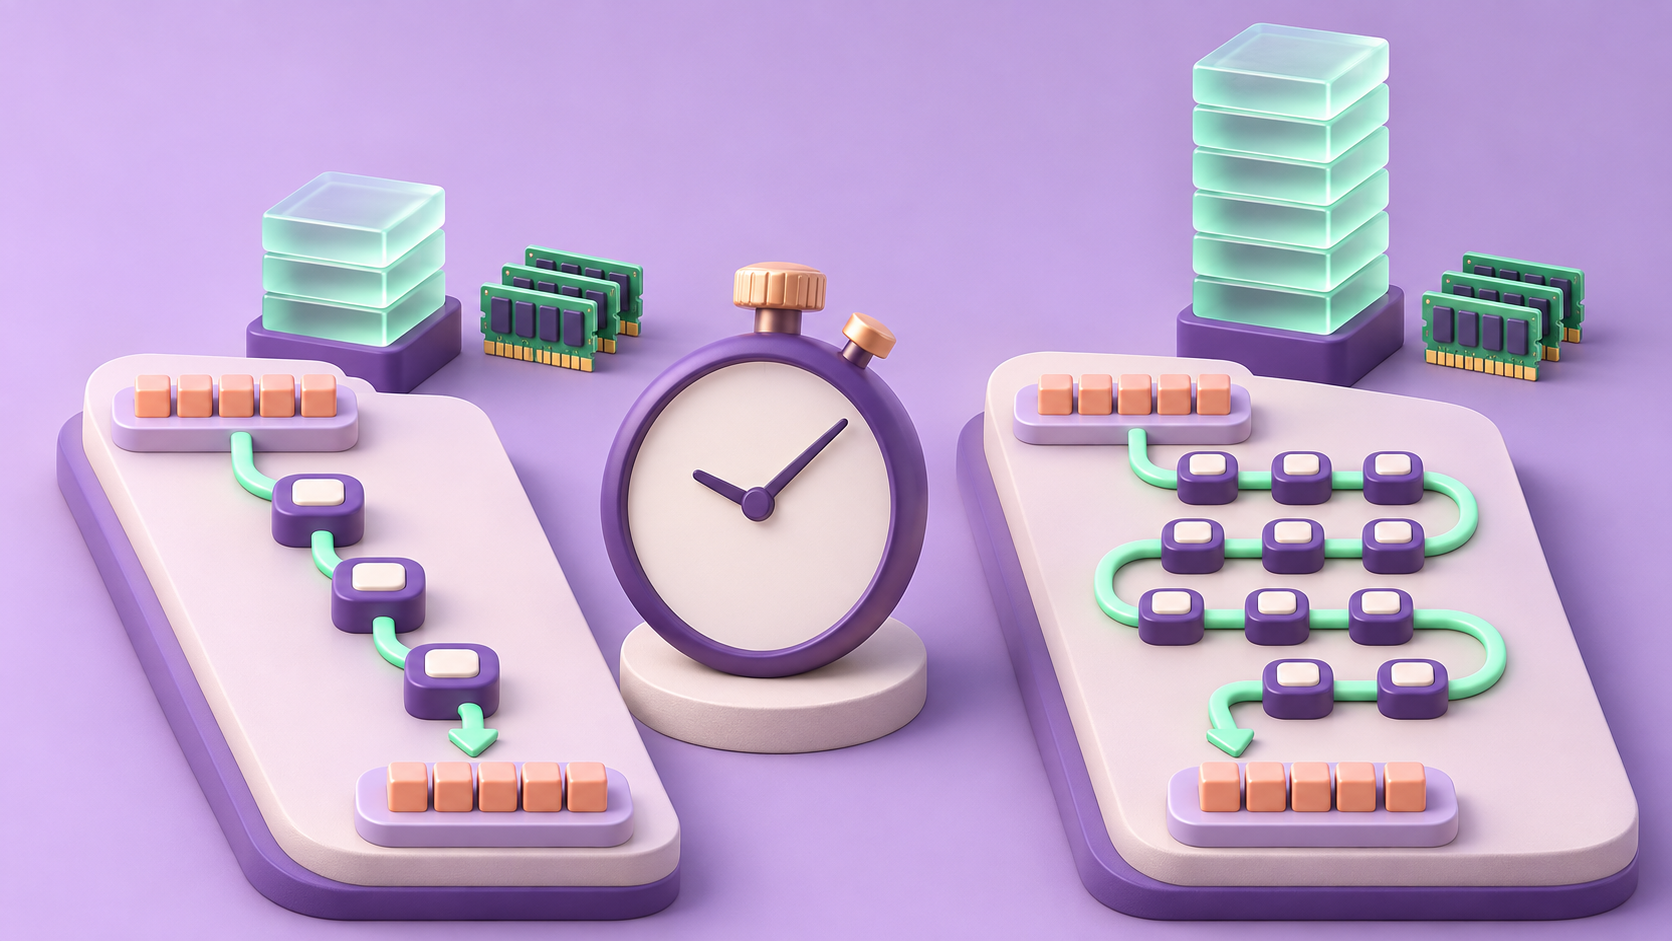
Modern high-concurrency systems demand the ability to process hundreds of thousands of simultaneous network connections without crashing server resources. Traditional operating system threads (1:1 kernel threading) incur severe memory and context-switching overhead that caps scalability at a few thousand concurrent threads. To solve the C10K and C1000K challenges, modern concurrency runtimes deploy user-space green threads and asynchronous message-passing paradigms: notably Go’s M:N work-stealing scheduler and the Erlang/Elixir Actor Model (BEAM).
1. The Limitations of 1:1 Kernel Threading: Memory and Context Switch Bottlenecks
In standard operating system threading models (POSIX pthreads in Linux or Win32 threads), each application thread maps directly to an OS kernel thread (1:1 threading).
While 1:1 threading leverages hardware multi-core parallelism directly, it hits severe physical scaling limits:
- Stack Memory Overhead: An OS kernel allocates a fixed stack (typically 2MB to 8MB) and a dedicated guard page per thread. Spawning 100,000 threads would require 800 gigabytes of RAM purely for thread stack reservations!
- Expensive Context Switches: Switching between kernel threads requires transitioning through kernel mode (ring 0), saving and restoring dozens of CPU registers, flushing floating-point state, and evicting CPU L1/L2 caches and Translation Lookaside Buffer (TLB) entries, consuming 1 to 2 microseconds per switch.
- Lock Contention: Shared-memory synchronization via mutexes causes kernel-level thread parking, context switching overhead, and priority inversions.
2. Go’s M:N Scheduler Architecture: The G, M, and P Model
The Go runtime solves this by multiplexing M green threads (Goroutines) onto N operating system kernel threads using an M:N Work-Stealing Scheduler. The scheduler coordinates three fundamental internal entities:
- G (Goroutine): Represents a lightweight execution thread. A goroutine begins with a tiny stack of just 2 Kilobytes, allocated dynamically on the heap. When stack space nears exhaustion, the runtime allocates a larger contiguous stack block and copies over the frames (contiguous stack allocation), expanding and shrinking dynamically up to 1 GB.
- M (Machine): Represents an actual operating system kernel thread managed by the OS scheduler.
- P (Processor): Represents a logical resource required to execute Go code. The number of Ps is bounded strictly by
GOMAXPROCS(defaulting to the number of logical CPU cores on the host machine). Each P maintains its own local run queue of runnable goroutines (holding up to 256 Gs).
The Work-Stealing Algorithm
To prevent CPU cores from sitting idle while others are overloaded, Go’s runtime implements a decentralized Work-Stealing Algorithm:
- A processor P continuously executes goroutines from its Local Run Queue. Because the local queue is owned by P, operations execute lock-free via atomic ring buffers.
- If P’s local queue is empty, it checks the Global Run Queue (locking it briefly).
- If the global queue is also empty, P attempts to steal half of the runnable goroutines from the local queue of a randomly chosen sibling processor P!
- If all queues are empty, the thread M associated with P goes to sleep until new work is scheduled.
Syscall Handling and Network Poller (netpoller)
When a goroutine executes a blocking operating system call (e.g. reading from disk), the runtime detaches the physical thread M from its logical processor P, allowing another thread M’ to bind to P and continue executing remaining goroutines. For network I/O, Go integrates directly with OS event loops (epoll on Linux, kqueue on macOS, IOCP on Windows) via the netpoller: blocking network reads simply park the goroutine in user space without blocking the underlying kernel thread M.
3. Cooperative vs. Preemptive Scheduling: Go’s Transition to Async Preemption
Early versions of Go relied on cooperative scheduling: a goroutine yielded execution only at function call boundaries where the compiler injected stack check preambles (morestack).
However, a tight CPU-bound loop lacking function calls (e.g., for {}) would monopolize the processor P indefinitely, causing GC safepoint stalls and starving other goroutines. Go 1.14 resolved this by introducing Signal-Based Asynchronous Preemption:
- A background system monitoring thread (
sysmon) inspects goroutines running longer than 10 milliseconds. - The runtime transmits an OS POSIX signal (
SIGURG) to the specific kernel thread M executing the offending goroutine. - The OS signal handler intercepts the thread, saves its register state, and rewinds instruction pointers to invoke the scheduler, preempting the goroutine gracefully.
4. The Actor Model: Erlang/Elixir BEAM and Akka Architecture
While Go utilizes CSP (Communicating Sequential Processes) with shared memory and typed channels, the Actor Model (conceived by Carl Hewitt in 1973 and popularized by Joe Armstrong in Erlang) enforces complete state isolation.
The Three Cardinal Rules of an Actor
An Actor is an autonomous computational entity that completely encapsulates its state and behavior. When processing a message, an actor can execute only three operations:
- Create a finite number of new actors.
- Send an asynchronous message to another actor whose address (PID) is known.
- Designate the behavior to be used for the next message it receives.
Crucially, Actors share zero memory state. All interaction occurs via immutable asynchronous message passing into the recipient actor’s private mailbox. This completely eliminates data races, deadlocks, and mutex lock contention.
Supervision Trees and ‘Let It Crash’ Philosophy
The Erlang BEAM runtime embraces failure as a natural operational condition. Instead of defensive error-handling code scattered throughout business logic, the system utilizes Supervision Trees:
- Worker actors focus strictly on happy-path execution.
- If an unexpected exception occurs, the worker actor crashes immediately.
- A parent Supervisor process intercepts the crash exit signal and executes a deterministic restart strategy (
one_for_one,one_for_all, orrest_for_one), restoring the system to a known clean state.
5. Comparative Concurrency Architecture Matrix
The following matrix contrasts the architectural mechanics of 1:1 OS threading, Go’s M:N Goroutines, and the Erlang Actor Model:
| Concurrency Engine | Threading Paradigm | Default Stack Size | Communication Paradigm | Fault Tolerance Architecture | Primary Production Strengths |
|---|---|---|---|---|---|
| POSIX pthreads / Java Threads (1:1) | 1:1 Kernel Threading | 2MB to 8MB (Fixed) | Shared memory with Mutexes / Locks | Thread uncaught exceptions crash process | Compute-heavy parallel math, graphics, C++ kernels |
| Java Virtual Threads (Project Loom) | M:N ForkJoin Scheduler | Dynamic (Continuation on heap) | Shared memory / Locks / CompletableFutures | Standard exception bubbling | High-throughput legacy enterprise Java web services |
| Go Goroutines (CSP) | M:N Work-Stealing | 2KB (Dynamic contiguous) | Channels (CSP) + Shared memory (sync/atomic) | Panics bubble up goroutine stack | High-performance microservices, Kubernetes, Docker, network proxies |
| Erlang / Elixir (BEAM Actor) | Preemptive Per-Process VM | ~300 Words (~2.4KB) | Zero-shared memory message passing | Supervision Trees (‘Let It Crash’ paradigm) | Telecom switches (99.9999999% uptime), WhatsApp messaging, IoT hubs |
| Rust Tokio (Async/Await) | Event-Driven State Machine | Zero stack overhead (Polled futures) | Channels / Mutexes via Arc | Standard Result |
Zero-cost network engines, Discord gateway proxies, Cloudflare edge |
6. Production Engineering Implementation: Lightweight Actor Engine Prototype in Python
Below is an enterprise-grade conceptual implementation demonstrating isolated actor mailboxes, asynchronous message dispatch, and supervision restart strategies:
7. Channel Architecture in Go: The Hchan Internals
Go’s channels (created via make(chan T, buffer_size)) are often viewed as magic language primitives, but under the hood, a channel is a standard C-struct called hchan:
- Lock Protection: Every channel operation acquires an internal mutex lock (
hchan.lock). Channels are not lock-free! - Circular Buffer: Buffered channels store elements in a circular array buffer (
buf) with read and write index pointers. - Wait Queues (recvq and sendq): When a goroutine attempts to read from an empty channel or write to a full channel, it cannot proceed. The goroutine allocates a
sudogdescriptor, appends itself to the channel’s wait queue, and callsgopark()to surrender its CPU thread. When a complementary operation arrives, the waiting goroutine is unparked directly and scheduled onto a P queue.
8. Frequently Asked Questions (FAQ)
Q: What is the initial stack allocation size of a Goroutine vs. an OS Thread?
A Go goroutine starts with only 2KB of stack memory, whereas an OS kernel thread typically allocates 2MB to 8MB. This 1000x difference allows a single server to comfortably run hundreds of thousands of goroutines simultaneously.
Q: Why does the Go scheduler need the logical ‘P’ abstraction?
The Processor P entity bounds the number of threads actively executing user code to GOMAXPROCS. If a thread M blocks on a disk syscall, P detaches and pairs with another idle M, keeping physical CPU cores 100% utilized without thread thrashing.
Q: What is Work Stealing in M:N schedulers?
When a processor P empties its local queue of runnable tasks, instead of going to sleep, it randomly inspects other processors and steals half of their pending tasks, maintaining even workload distribution across all CPU cores.
Q: What is the ‘Let It Crash’ philosophy in Erlang/Elixir?
Instead of writing complex defensive try-catch blocks to anticipate every edge case, Erlang developers let failed processes crash immediately. Supervision trees catch the exit signal and restart the process with a clean initial state.
Q: Why don’t Actors experience data races?
Actors do not share memory. Each actor maintains strictly private state that can only be mutated by that actor processing messages sequentially from its mailbox. Without concurrent shared memory access, data races are impossible.
Q: How does Go 1.14 handle tight loops without function calls?
Go 1.14 introduced asynchronous preemption via OS signals (SIGURG). A background sysmon thread signals running threads after 10ms, pausing execution and descheduling the goroutine even if it has no function call boundaries.
Q: What is the difference between Buffered and Unbuffered Channels in Go?
Unbuffered channels have zero capacity and enforce synchronous rendezvous: the sender blocks until the receiver is ready. Buffered channels decouple execution by storing messages in an internal ring buffer up to the buffer capacity.
Q: What is Project Loom (Virtual Threads) in Java?
Project Loom introduces lightweight user-space threads (Virtual Threads) to the Java platform. Like goroutines, virtual threads are scheduled by a ForkJoinPool onto carrier OS threads, enabling millions of concurrent tasks in standard Java.
Q: How does the netpoller optimize network I/O in Go?
The netpoller integrates with OS multiplexing APIs (epoll/kqueue). When a goroutine calls net.Conn.Read(), the socket is marked non-blocking. If no data is available, the goroutine is parked and registered with epoll, freeing the kernel thread to run other work.
Q: What happens when an unbuffered channel in Go has no receiver?
Sending to an unbuffered channel with no receiver parks the sending goroutine indefinitely. If all goroutines in the program become parked with no work remaining, the runtime detects a fatal deadlock and panics.
Q: How does Erlang ensure fair scheduling across millions of actors?
The BEAM virtual machine assigns a reduction budget (typically 2,000 reductions or function calls) to each process. Once the budget is exhausted, the process is preempted and placed at the back of the run queue, preventing starvation.
Q: What is the difference between CSP (Go) and the Actor Model (Erlang)?
In CSP, communication focuses on the intermediary channel: senders do not know who receives the data. In the Actor Model, communication focuses on identity: messages are addressed directly to a specific actor’s PID.
9. Architectural Conclusion and Engineering Recommendations
Modern concurrency runtimes represent the ultimate triumph of user-space scheduling over rigid OS kernel primitives. When architecting high-scale distributed systems:
- Standardize on Go (M:N Work Stealing) for high-throughput network proxies, microservices, and cloud infrastructure requiring low memory footprints and simple channel-based synchronization.
- Deploy Erlang/Elixir (BEAM Actor Model) for fault-tolerant telecommunications, real-time messaging fabrics, and mission-critical distributed systems requiring zero-downtime hot code upgrades and supervision trees.
- Adopt Java Virtual Threads (Project Loom) to modernize legacy enterprise thread-per-request architectures without rewriting synchronous blocking codebases.
- Avoid unconstrained 1:1 Kernel Thread Spawning in high-concurrency environments to prevent severe memory exhaustion and context-switching thrashing.